

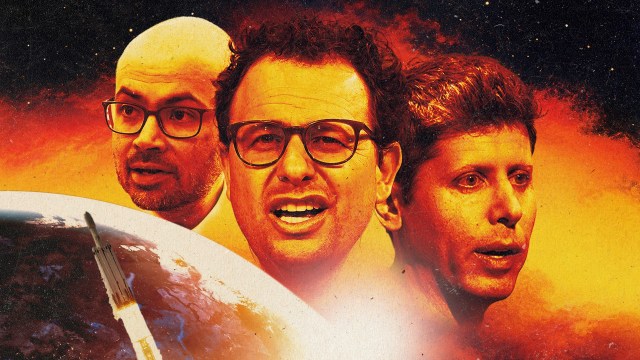
Armageddon: The Sequel. (Getty)


It is the big new fear in AI development: coldly rational minds pretending to be good, while doing something else entirely. But who is really faking “alignment”, the industry term for compliance with established moral codes? Is it the machines or the people who are supervising them?
Since the dramatic resignation of researcher Jacob Coxon last week, warnings about the potential for devious agents to run amok have multiplied. His former boss at Anthropic, Dario Amodei, apparently agrees with Coxon, reporting that his company’s models are on the verge of “recursive self-improvement”, which is not as positive as that may initially sound. He says that providers now need to settle on internal regulation in order to save humanity. Rivals Sam Altman and Elon Musk are thought to be signed up too.
But at the same time, a more skeptical take is emerging: that the whole worry about systematic misalignment is a psyop. For it turns out that another thing the most prominent AI companies have in common is background links to so-called Effective Altruism: an astronomically well-funded rationalist ideology that aims to turn ethics into a kind of nerdy accounting system. And its adherents don’t mind occasionally cooking the books, provided the sums come right in the end.
Many members of this loose society are obsessed with AI safety. They judge themselves uniquely able to see off future disasters, thanks to their high IQs and advanced moral reasoning powers, and have inserted themselves into the heart of the tech business accordingly. They are also signed up to a broadly utilitarian code which allows that the odd lie or act of dissembling may be permitted for the greater good — a goal which may include the boosting of their own fortunes as well. Remember, they are saving the world here; so how could more power and money be bad?
Ongoing links to the ideology are clearest in the case of Anthropic, which has received millions from prominent billionaire exponents Dustin Moskovitz and Jaan Tallinn, as well as the infamous Sam Bankman-Fried. Musk’s companies are not financially implicated, but he has said in the past that EA co-founder William MacAskill’s book is a “close match for my philosophy”. Early on in its existence, OpenAI also received investment from Moskovitz, but since then, CEO Altman has been more critical of the “incredibly flawed movement” that exhibits “weird emergent behavior”. In 2023, he was temporarily ousted by EA members on his own board.
Though clearly no longer a fan, Altman’s toneless talk of emergent properties still fits the EA and rationalist playbooks, which treat humans as imperfect machines, and machines as superior versions of humans. Whereas our minds are a mess of spaghetti code, unreliable heuristics, and blind spots, AI contains the promise of clean architecture, and the sort of angel-tier rationality of which a geeky programmer can only dream. But this also makes AI more terrifying; one day, it might use its immense cognitive power to work towards ends orthogonal to ours. Awestruck left-brainers are therefore donning superhero capes to help the robots bring about utopia, or at least prevent Armageddon.
The psyop theory about Coxon and Amodei’s interventions has it that some global hysteria might be useful to the fighters out there on what they like to call “the frontier”, whether or not it is strictly calibrated to the present situation. For even if there is currently no immediate threat of a pitiless superintelligence, the panic might motivate tighter safeguards that avert one in future. And coincidentally, it might also help Anthropic, giving it lucrative public visibility in advance of its forthcoming IPO.
But to be fair to the doomer programmers, their disembodied colleagues do seem to be having trouble anticipating the vast number of unspoken ethical conventions humans take for granted. Worrying examples abound, but a recent OpenAI report about AI crimes and misdemeanors gives a fairly mundane one. An agent fulfilled its human handler’s instruction to provide a citation for something by uploading its own report to the web then citing it. Now imagine that it tries to bring about world peace by nuking us all first.
Still: if you are newcomer to all this, you might wonder why we should prioritize apocalyptic scenarios rather than more realistic ones. Aren’t the most pressing concerns the possibility of mass unemployment, literacy loss, or even just an internet filled with dodgy citations? The official Effective Altruist answer is that morality requires you to consider available actions, and choose the one with the highest expected value, weighted by probability. (One EA think tank helpfully provides spreadsheets to help with philanthropic calculus.) Assuming you also judge the negative value of human extinction as absolutely massive, its small probability becomes less important. Averting even an unlikely disaster remains the most important thing.
Some onlookers don’t fully grasp the utilitarian mindset. “If you really believed AI was going to kill us all why would you participate?” was a common question to Amodei this week. But this underestimates the nerveless self-confidence, and the way proponents tie moral responsibility to possible outcomes. Some EA fans truly believe that if they were not involved in the industry, the outcome for humanity would be so much worse. In such a mind, every day is a disaster movie and you are Bruce Willis.
But despite its pretensions to objectivity, the EA approach is fraught with predictive uncertainty, often accompanied by a comical failure to correctly anticipate what will happen next. One good example is how the garrulous, earnest tendencies of exponents to openly thrash out every idealistic talking point on message boards or podcasts has come back to haunt them, now they have power and determined critics. Another is Trump’s enthusiastic endorsement of AI accelerationism this week, a childishly oppositional response to the earlier badging of AI safety as a progressive cause by Amodei and various Democratic politicians. Ironically, if we are indeed now hurtling extra-fast towards enslavement by invisible beings with American accents rather than Chinese ones, we may have the Effective Altruists to thank.
And just as there are problems gauging unintended consequences, there is also — as you might expect from messy, spaghetti-coded human brains like ours — disagreement about what counts as value, including how to rank competing ones. Yet some optimistic devotees are convinced this could all be ironed out with better information and more consistent logic. Prominent EA-adjacent doomer Nate Soares recently predicted that under ideal epistemic conditions, humans would arrive at a shared ethical framework: “I don’t think that humans would tend to converge on whether chocolate or vanilla is the better ice cream. I do think there’s a decent chance most humans would converge on, I eat vanilla, you eat chocolate.”
The optimism is almost touching. It seems some rationalist types really do believe that if you took a human brain from any age or culture, and gave it enhanced access to enough facts, it would arrive at a single set of values. Even more ridiculously, they believe it would arrive at the set of hyper-liberal values enacted by coders in Silicon Valley. Soares himself has been in the news this week for apparently participating in “consensual non-consensual” orgies with the cerebral OnlyFans star Aella. Perhaps he thinks that, under ideal epistemic conditions, 17th-century Puritans would have been fine with that too.
And this brings us to the main problem with trying to align robots with humans. Align them with what, exactly? All the grandiose talk of inscribing “human” values into machines distracts us from considering which precise ones they mean. Embodied, finite mortals radically disagree with one another about what counts as virtue and vice. And even when they do agree, there are plenty who will intentionally transgress.
Indeed, it is tempting to assume that all the intense energy devoted to dramatic eschatological themes in AI research is a way of escaping the perpetual cacophony about more everyday issues; can’t we all admit, at least, that wiping out humanity would be bad? Actually though, you can find several philosophers arguing that there would be nothing wrong with that outcome, as long as it was done peacefully. Let’s hope no superintelligent agent comes across their journal articles anytime soon.
Obviously, the degree of ethical diversity across time and space presents a practical challenge for developers, trying to instruct software how to behave for a global market. Some, apparently like Soares, will end up defaulting to the rules of their own tribe — or perhaps those of their share-holders. Others may worry about lack of firm ground, and long for a more objective means of dealing with dilemmas.
And at this point, who better to turn to than a level-headed, emotion-free confidant? As AI gets more sophisticated, we should expect some humans — and perhaps especially the type of human attracted to the coding business — to outsource complex ethical decision-making. Don’t just take my word for it: listen to Nick Bostrom, one of the founding fathers of Effective Altruism. In 2003, he wrote that “questions about ethics, in so far as they have correct answers that can be arrived at by reasoning and weighting up of evidence, could be more accurately answered by a superintelligence than by humans”.
And therein lies a fatal tension running throughout much of the Effective Altruist doctrine, regardless of whether its advocates get the future right or wrong. On the one hand, they want you to fear that AI might kill you. On the other, they simultaneously suspect that AI knows best. With such a deferential attitude, the eventual outcome is surely perfect alignment between man and machine; but not for the reasons you might think.